Current-generation accelerators
NVIDIA H100 and A100 instances for training runs, fine-tuning and production inference.
GPU capacity for teams training and serving models, available on demand or reserved. The point of running it ourselves is control over where the hardware sits, what it costs and what powers it.
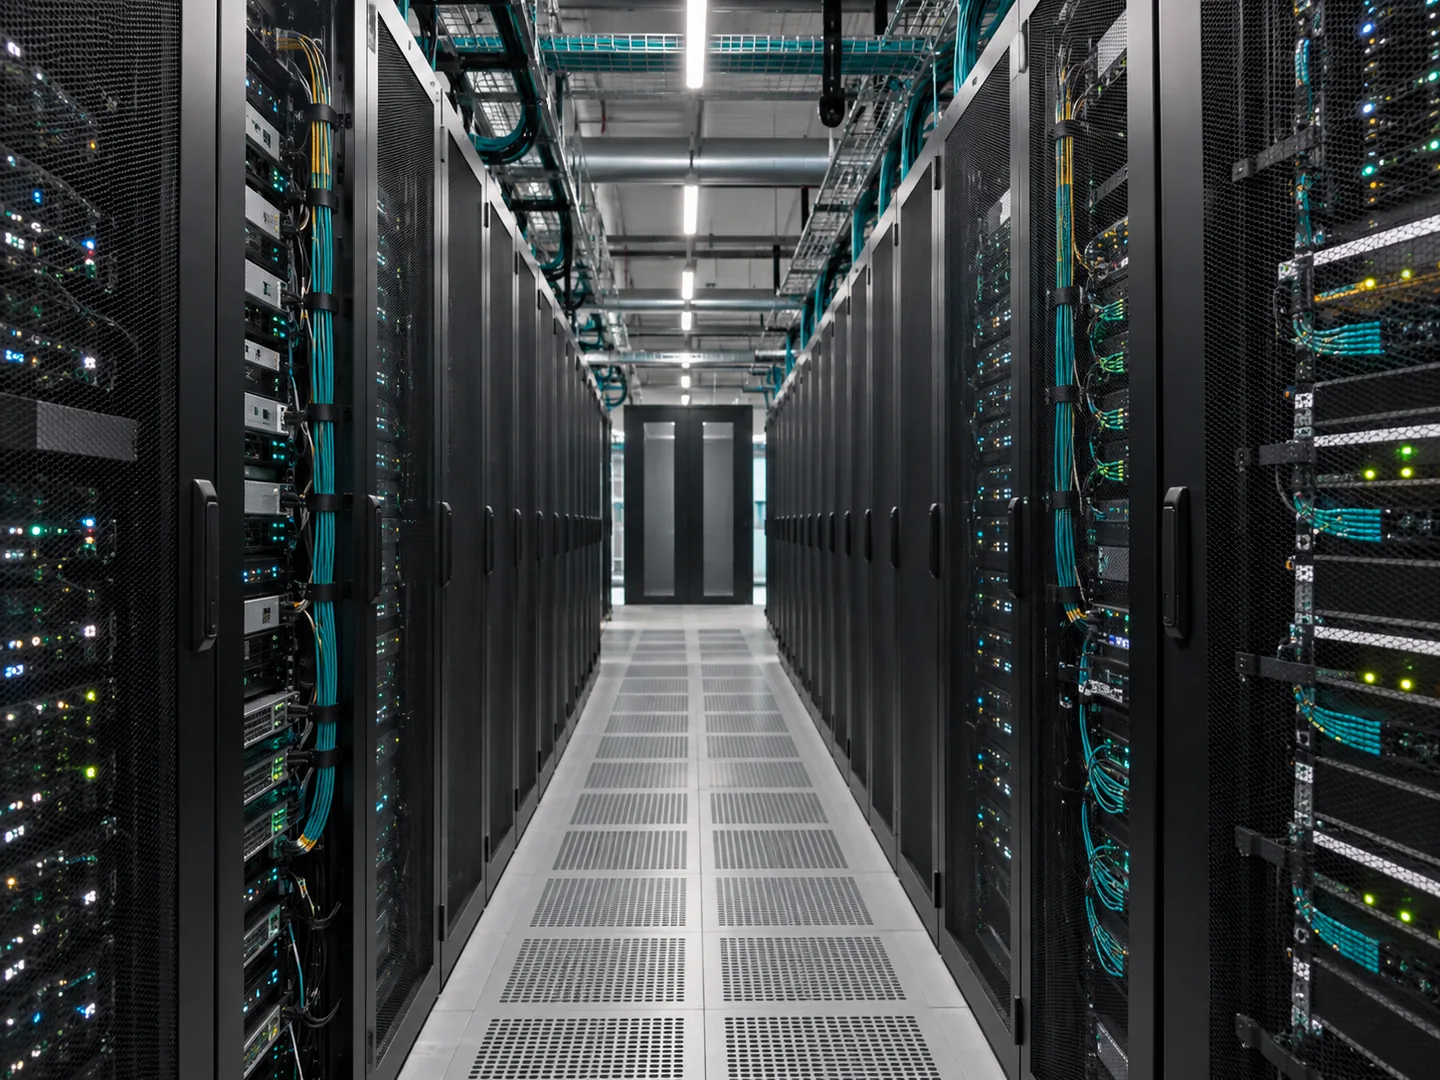
NVIDIA H100 and A100 instances for training runs, fine-tuning and production inference.
PyTorch, TensorFlow, JAX, CUDA and the usual serving and MLOps stack, with no proprietary wrapper to learn.
Hosted in Indian data centres, which matters when data residency is part of the requirement.
In December 2025 we signed a memorandum of understanding with the Government of Telangana for a 50 MW AI and hyperscale data centre across 20 acres at Fab City, Tukkuguda, an investment of about Rs 4,000 crore. The GPU platform is what that capacity is intended to serve.
Training and fine-tuning runs that need multiple GPUs for days at a time, inference endpoints that need predictable latency, and batch work such as embeddings, evaluation and data processing. Reserved capacity suits steady workloads; on-demand suits experiments.
For regulated customers the deciding factor is often jurisdiction rather than price. Running in Indian facilities keeps workloads and data on shore, which is a requirement we are seeing more often in finance, health and government work.
Multi-GPU runs for training and fine-tuning open models.
Served endpoints where latency and cost per request both matter.
Simulation, computer vision and scientific computing.
Yes. Reserved capacity is the usual arrangement for sustained training or production inference; on-demand suits shorter experiments.
In Indian data centres, including the Telangana facility we are developing. If you have a residency requirement, tell us and we will confirm the location in writing.